
Fifty AI ideas give you a queue, not a roadmap. Each request carries a sponsor who thinks their department is the exception. Turn every request into the same decision record, score the records against the same rules, map the prerequisites, and fit the survivors into real capacity over twelve months. That is the portfolio problem a fractional AI officer is there to own. The NIST AI RMF Core treats this as an iterative lifecycle rather than a one-time ranking exercise.
Turn Fifty AI Ideas Into a Twelve-Month Delivery Sequence
Editorial Team · Sep 1, 2026 · 17 min read
Researched and drafted with AI assistance by the AgentClaw Editorial Team. Sources checked Sep 1, 2026. Passed AgentClaw's automated editorial review. No human reviewer was involved.
- ai-portfolio
- ai-roadmap
- ai-governance
- prioritization

TL;DR
- A row earns a place in the sequence when it carries an outcome, baseline, dependency, risk, capacity demand, budget, owner, and evidence date.
- Score value, evidence confidence, readiness, adoption effort, risk exposure, and learning leverage. Apply hard gates before ranking the survivors.
- The highest score does not win if its dependency is missing or its owner cannot protect the capacity. A sequence is a constrained portfolio, not a sorted list.
- Review monthly, re-forecast quarterly, and record the evidence that would continue, reshape, pause, or stop each initiative.
A backlog is not a delivery sequence
A backlog says what people want. A delivery sequence says what the company will fund first, what must happen before it, who is accountable, how much attention it consumes, and what evidence can change the decision. Those are different documents. Pretending otherwise is how every department becomes priority one.
Build one full use-case register first. The Federal Reserve's public inventory is useful because it treats an AI use case as a record that is inventoried and updated, not a slide that disappears after the steering meeting. Its AI Use Case Inventory is published at least annually under OMB requirements. Canada's Algorithmic Impact Assessment tool makes the same point from a risk angle: the assessment collects project, system, algorithm, decision, impact, and data information before the risk score means anything.
Do not start by asking which department has the most enthusiasm. Ask whether every idea has enough information to be compared. If a row cannot name its business outcome, current baseline, accountable owner, likely dependency, risk boundary, capacity demand, budget envelope, and next evidence date, call it an unformed request. Put it in discovery and give it a date by which the missing facts must exist.
That distinction protects the people doing the work. A weak request does not lose because finance shouted louder. It loses because the sponsor has not supplied the evidence required for a funding decision.
Score six things before you sort the list
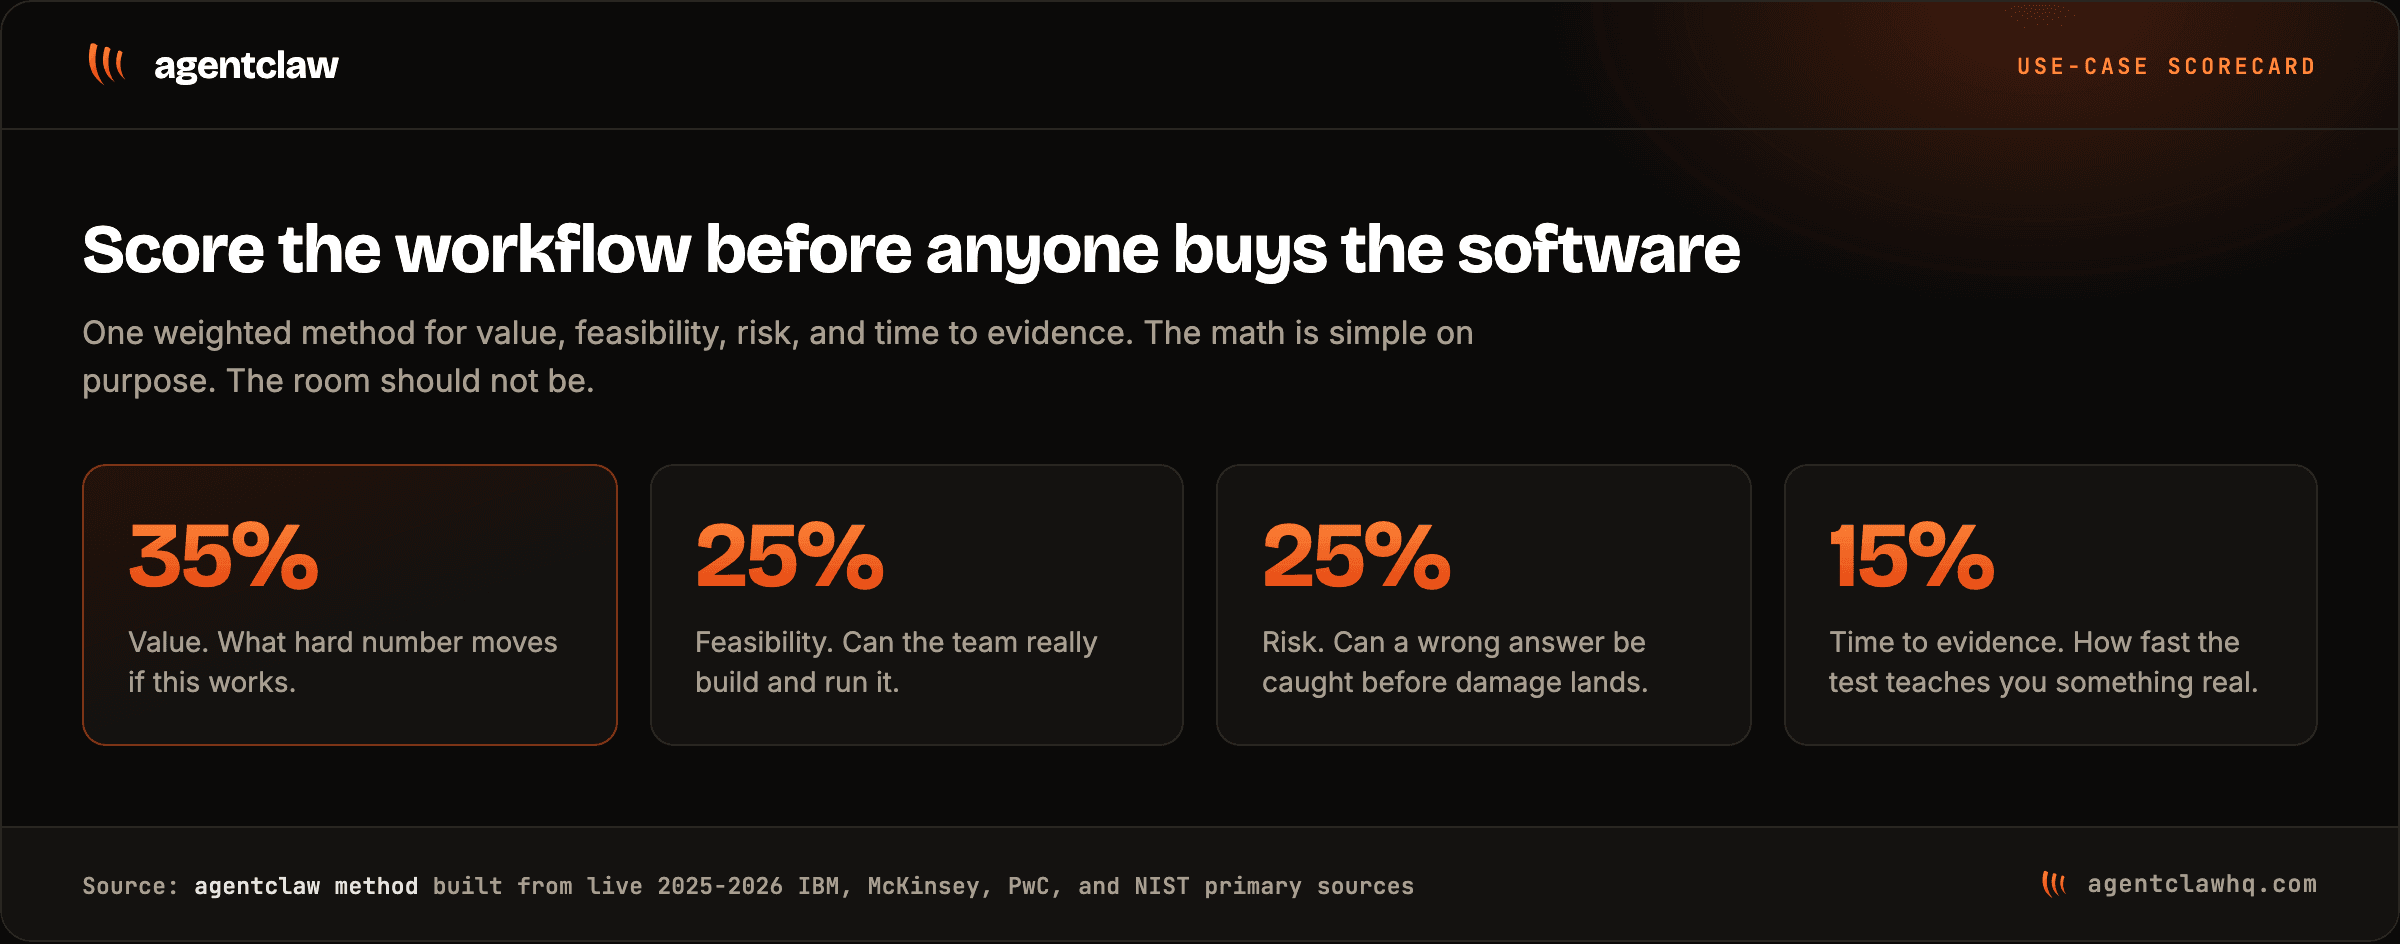
A useful score does not pretend to know the future. It makes the assumptions visible enough for the sponsor to challenge them. Score each candidate from 0 to 5 on six dimensions: outcome value, evidence confidence, operational readiness, adoption effort, risk exposure, and learning leverage. Start with these weights: value 30 points, confidence 20, readiness 15, adoption effort 15, risk exposure 10, and learning leverage 10. The total is 100 points.
Value asks which measurable business outcome changes and by how much. Confidence asks what is already observed rather than promised. Readiness asks whether the process, data, permissions, and vendor route exist. Adoption effort asks how much change the people doing the work must absorb. Risk exposure asks what happens when the system is wrong, unavailable, biased, or used outside its intended context. Learning leverage asks whether the work tests a reusable capability or only produces a one-off demonstration.
Use the weighted score as a conversation starter, not an automatic funding decision. A high value score with a zero baseline is a hypothesis. A high readiness score with no accountable owner is a trap. A low learning score can still be correct for a mandatory control. Mark mandatory work separately so a statutory, safety, or continuity obligation does not compete with a discretionary productivity idea.
NIST's AI Risk Management Framework Core gives the governance backbone for this treatment. Its functions are Govern, Map, Measure, and Manage, and it says they are not a checklist or a fixed ordered sequence. That is why the score needs both opportunity and control fields. The NIST AI RMF Playbook adds suggested actions, but it also warns that organizations should select what fits their context rather than follow every suggestion.
Ask one narrow question: if this candidate is allowed into the next decision, what makes it more defensible than the other candidates? If the answer is only that its sponsor wants it, score it zero for evidence confidence and keep moving.
STARTING WEIGHTS
Evidence and value get 50 of the 100 points
Start with this six-factor model. Publish any changed weights with the roadmap version.
Outcome value
30 points
Evidence confidence
20 points
Operational readiness
15 points
Adoption effort
15 points
Risk exposure
10 points
Learning leverage
10 points
Source: AgentClaw editorial framework (2026) · Weights are an original starting model informed by NIST's Govern, Map, Measure, and Manage functions.
Apply hard gates before the ranking
Some ideas should not be ranked beside ordinary workflow improvements. They need a gate first. Ask four questions. Is the intended purpose clear? Is the affected process and data known? Is a human decision owner named where human judgment matters? Is there a credible control for the main failure mode? Any no keeps the candidate in discovery, sends it to a fixed-scope data or process project, or declines it.
This is where risk becomes a sequencing input rather than a compliance paragraph at the end. The EU AI Act describes risk management for high-risk AI systems as a continuous iterative process across the lifecycle, including identifying foreseeable misuse, evaluating risks, and adopting targeted measures. Read Article 9 of the regulation as a reminder that a risk record needs a treatment and a review, not only a label. The Model AI Governance Framework for Agentic AI likewise emphasizes human accountability and lifecycle controls.
Do not turn this into a giant approval board. A gate is a short answer with a named next action. For a customer-facing assistant, the gate might require an approved source set, a human escalation route, and a sample of failure cases before pilot. For an internal drafting tool, the gate might require data classification, an owner for the final output, and a rule that nothing sends without review.
Keep the gate result visible in the register: pass, discovery, redesign, or decline. A candidate can score 92 and still be a no if the company cannot explain who is accountable when it fails. That is not bureaucracy. It is the cheapest point at which to notice that the proposed benefit depends on an authority nobody has granted.
Map dependencies before you assign months
A score is a ranking. A dependency map turns the ranking into an order. Draw a directed edge for every condition that must be true before an initiative can start or pass its next gate. Use plain labels: data, permission, process definition, vendor decision, training, measurement, or decision authority. Give each edge an owner and a required evidence date.
The UK's Public Sector AI Governance Operating Model makes these relationships visible through strategic, tactical, operational, and continuous-assurance layers. It names lifecycle phases, evaluation evidence, audit trails, decision logs, RACI ownership, and failure-mode testing. The model is public-sector guidance, not a private-company mandate, but the portfolio lesson travels: a live use case is not ready because a model demo exists.
The OECD's accountability report spells out the same dependency. It describes phases from planning and design through data, model building, validation, deployment, and operation, with risk management feeding back into the next decision. Use that loop in the map. If initiative B needs a clean customer definition from initiative A, B does not get a month because its score is higher. B gets a conditional month after A's evidence gate.
Three dependency patterns matter. A hard prerequisite blocks the next stage. A shared capability, such as identity or evaluation data, can support several candidates and deserves portfolio treatment. A contested dependency means two sponsors are asking for the same scarce owner, vendor, or change window. Mark the pattern rather than hiding it inside a comment.
Find the critical path too. It is not the longest list of tasks. It is the chain where one late decision moves several later commitments. Fund and staff that chain before you promise the attractive leaf projects attached to it.
Stress-test the sequence against capacity and budget
Now replace enthusiasm with arithmetic. Ask how many hours each initiative needs from each constrained role in each month, not how many people appear on the org chart. Count the business owner, subject-matter reviewers, data steward, procurement or legal reviewer, and delivery capacity. A company with no internal software, firmware, or embedded-code writer still has real capacity constraints. The bottleneck may be the operations manager who has to validate every exception or the finance lead who owns the baseline.
Use a conservative capacity envelope. If the accountable owner can protect 60 hours in a month, do not promise 60 hours of named work. Reserve room for incidents, decisions, vendor questions, and the work that keeps the business alive. Put the reserve in the model and say what it is.
The General Services Administration's AI directive ties prioritization to risk tolerance, capacity for AI-ready data, workforce needs, procurement, monitoring, and the ability to terminate non-compliant systems. The Federal Reserve AI Use Case Inventory is a useful reminder that a portfolio needs a maintained record, not an annual slide. Those are the fields a budget review needs.
Budget has three layers. First, the initiative cost to test or deploy. Second, the operating cost to run it, including review time and vendor usage. Third, the enabling cost that makes later initiatives cheaper or safer. If a vendor quote covers only the first layer, it is not a business case. If a proposal has no amount for monitoring, training, or exception handling, the estimate is incomplete.
Assume 60 owner-hours are available. Discovery uses 16 hours, a bounded build uses 32, governance review uses 8, and incident reserve uses 8. One discovery plus one build consumes 48 hours and can run. Two discovery items plus one build consume 64 hours, so the call is conditional: add capacity or reduce discovery. The table shows the tradeoff before it reaches the calendar.

Show the data behind this diagramHide the data behind this diagram
| Combination | Call | Reason |
|---|---|---|
| One discovery + one bounded build | Run | 48 owner-hours stays under the 60 owner-hour capacity line. |
| Two discovery items + one bounded build | Conditional | 64 owner-hours needs additional capacity or reduced discovery. |
| One bounded build + two governance reviews | Run | 48 owner-hours leaves 12 hours for the incident reserve. |
| Two bounded builds | Conditional | 64 owner-hours needs additional capacity or a reduced build scope. |
Turn the surviving rows into twelve months
Do not fill twelve columns with fifty colored bars. Build the sequence in horizons, then attach dates only where the evidence is strong enough. Month 1 is for the register, baselines, hard gates, and owner decisions. Months 2 and 3 are for the enabling work that several candidates share: data definitions, permissions, vendor selection, evaluation cases, and the first governance controls.
Months 4 through 6 should carry one bounded production path and one learning path. Every department does not get a pilot. The production path proves a useful workflow under a named owner. The learning path resolves a high-value uncertainty that would change later sequencing. Months 7 through 9 are for the next use case that benefits from the first path's capability, with a stop or reshape gate before the spend expands. Months 10 through 12 are for scale only when the evidence supports it, plus a portfolio reset for the next year.
The OECD lifecycle guidance says lifecycle phases can be iterative and are not necessarily sequential, while the UK operating model distinguishes pilot, managed beta, beta, and live stages. Use both ideas together. The calendar can be sequential while the evidence loop remains iterative. A pilot that misses its baseline does not earn a beta month because the bar moved.
Every quarter needs a portfolio decision, not only a status update. Continue when the evidence meets the stated threshold. Reshape when the outcome still matters but the route is wrong. Pause when a dependency or owner is missing but the option remains worth preserving. Stop when the expected outcome, risk boundary, or capacity case no longer holds. Write the trigger before the work starts. Otherwise sunk cost will make the decision for you.

Show the data behind this infographicHide the data behind this infographic
- Month 1: complete the use-case register, baselines, hard gates, and accountable owners.
- Months 2-3: fund shared data, permissions, vendor, evaluation, and governance foundations.
- Months 4-6: run one bounded production path and one learning path.
- Months 7-9: expand only after a stop or reshape gate confirms the evidence.
- Months 10-12: scale proven work, retire weak work, and reset the next portfolio.
Make every row survive the review meeting
A roadmap row is ready for a funding conversation when somebody outside the project can inspect it without calling the sponsor for context. Keep these eight fields together: outcome, baseline, dependency, risk, capacity, budget, owner, and evidence date. Add the current stage and decision trigger so the next review has somewhere to land.
The owner is a person with authority to keep the work inside its boundary, not a department name. The evidence date is when a named artifact or measurement will exist. It is not the date somebody hopes to feel confident. A useful evidence entry says what will be inspected: a sample of 200 outputs, a signed data definition, a procurement decision, a measured exception rate, or a user review at a stated stage. "process in place" is not evidence. It is a way to postpone the uncomfortable sentence.
The Federal Reserve inventory and Canada's AIA guidance show why the register needs enough detail to be checked. GSA's directive also calls for measurement, monitoring, evaluation, reporting, risk assessment, and termination of non-compliant systems. These documents serve different public-sector purposes, so do not copy their legal obligations into a private company. Use their record discipline instead.
Set the cadence before the portfolio gets busy. Review active work monthly. Re-forecast the whole sequence quarterly. Trigger an exception review when a material dependency changes, a risk crosses its threshold, a baseline moves, an owner loses capacity, a vendor changes terms, or a production incident arrives. Keep the old decision beside the new one so leadership can see what changed and why.

Show the data behind this infographicHide the data behind this infographic
- Outcome: the measurable business change the initiative is meant to create.
- Baseline: the current condition and the method used to measure change.
- Dependency: the prerequisite, shared capability, or contested resource.
- Risk: the failure mode, affected people, and control boundary.
- Capacity: the constrained roles and hours required in each phase.
- Budget: test cost, operating cost, and enabling cost.
- Owner: the accountable person with authority to act.
- Evidence date: the next dated artifact or measurement that changes the decision.
Decide whether the portfolio needs an owner
If the register is already clean, the scoring rules are agreed, the dependency owners are named, and somebody has time to run the monthly review, you may not need a new leadership layer. You need a portfolio owner to keep the system alive.
If fifty requests sit across departments with no person empowered to reject, sequence, fund, or stop them, the gap is not another workshop. It is ownership. The public GSA directive places AI leadership, governance boards, risk tolerance, prioritization, capacity, monitoring, and termination in one operating picture. A non-software company does not need to copy a federal structure, but it does need one accountable person who can carry those decisions across department lines.
That is the work we take on through our AI strategy service: turn the requests into a maintained register, connect the score to the dependency and capacity view, and run the decision cadence with the people who own the outcome. We do not pretend the score chooses for leadership. Leadership still decides what it is willing to fund, what risk it will accept, and which owner has the authority to say no.
The boundary matters. Our canonical pricing page separates four offers. CAIO Core starts at $5,000/month for ongoing executive AI ownership, with builds separately scoped. CAIO + Delivery starts at $10,000/month and adds an ongoing delivery pod with one active build stream. A Starter build is $1,500 to $2,500 fixed, and a Production sprint is $5,000 fixed for one workflow in about two weeks without ongoing executive ownership. If the problem is one known workflow, buy the project. If the problem is fifty competing requests and nobody can defend the order, buy ownership.
What breaks the sequence
Four failure modes show up again and again. The loudest sponsor wins when the register has no common fields. Require the same row structure and publish the scoring weights. Quick wins can consume all the capacity, leaving the shared foundation unfunded. Reserve explicit foundation and governance capacity. A high-scoring candidate can enter the calendar before its dependency is owned. Add a hard prerequisite edge and a dated evidence gate. A pilot can continue because nobody wrote the stop condition. Record the threshold before the pilot begins.
NIST's 2026 report on monitoring deployed AI systems describes post-deployment monitoring as necessary for checking real-world reliability, unexpected outputs, and consequences. That is a direct warning against treating launch as the end of the roadmap. Monitoring belongs in the original capacity and budget row.
Watch the false precision of the score too. A 78 is not more truthful than a 74 when both numbers came from a sponsor's guess. Keep a confidence note beside every rating and use the next evidence date to improve the estimate. If the score changes, the sequence can change. That is the system working, not the plan failing.
The honest output after this exercise may be smaller than the company hoped. That is good. Twelve months with two production paths, one shared foundation, and clear stop decisions is a delivery sequence. Twelve months with nine pilots, no baseline, and every sponsor still calling their idea urgent is theater with a calendar attached.
Questions that change the decision
Should every department get one AI initiative in the twelve-month plan?+
No. Put every department's candidates in one portfolio, then balance the portfolio against outcome value, evidence, dependencies, risk, capacity, and budget. A department can remain represented in discovery without receiving a production slot.
What if the highest-scoring AI idea depends on work that is not funded?+
Do not put the dependent idea on the calendar as if it were ready. Fund the prerequisite, create a dated evidence gate, or reshape the idea so it can run within the current boundary. The dependency is part of the decision, not a footnote.
How often should an AI portfolio be reprioritized?+
Review active work monthly and re-forecast the full twelve-month sequence quarterly. Trigger an earlier review when capacity, risk, baseline, vendor terms, dependencies, or production evidence changes materially. The NIST AI RMF Core frames AI risk work as iterative across its functions.
Can a company without software engineers run this process?+
Yes, if it has named business owners, access to the relevant data and processes, and a delivery route that fits its boundary. The portfolio owner does not need to write software. They do need authority to decide, evidence to inspect, and a safe way to involve a builder when a build is approved.
When is a fractional AI officer the wrong answer?+
If you already know the one workflow to fix, the right buy may be a Starter build or Production sprint. If AI is the product you sell or an employee writes software, firmware, or embedded code, this strict operating model is not the fit. If the problem is competing priorities, missing ownership, and a sequence nobody can defend, the fractional role is relevant.
Stop calling fifty requests a roadmap
The free AI ownership assessment is a six-question qualifier for a non-software company where no employee writes software, firmware, or embedded code. It identifies whether executive AI ownership, a scoped build, or no engagement is the honest next step.
The assessment is a six-question qualifier for companies that fit the ownership model.
Produced by
Related reading



the memo
One useful AI ownership decision, when we have one.
What we would decide, govern, measure, or build, minus the pitch. We write when there is something worth sending, and you can reply to any email to come off the list.